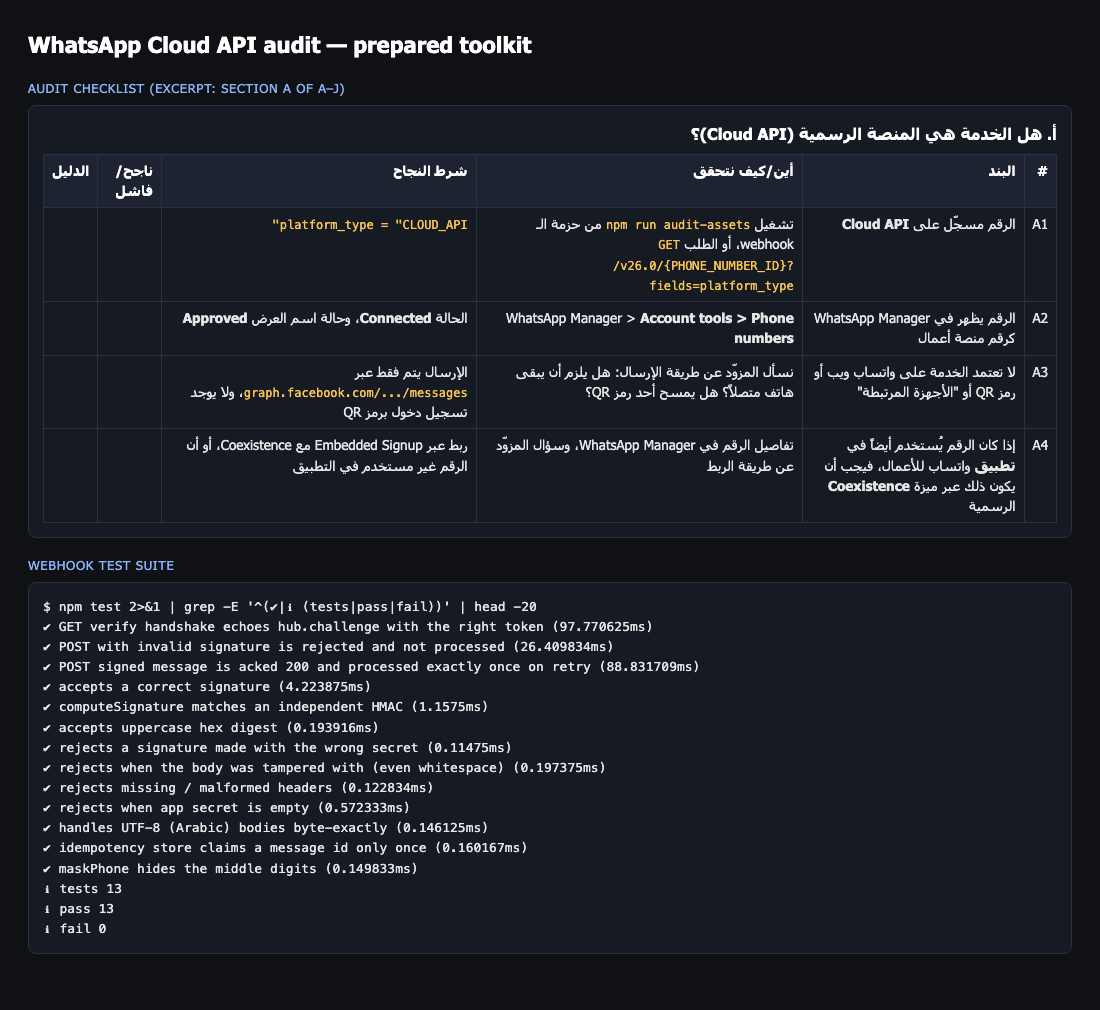
13/13tests passing
WhatsApp Cloud API audit and a secure webhook
A toolkit that shows whether a WhatsApp integration is really official and who owns it, plus a webhook that verifies Meta's signature and never processes a message twice.
Diagnosing a slow local model: the cause wasn't the hardware but a full swap file. Then tuning and measuring about 20 models.
Measured result
6 → 37
tokens per second
A 35B-parameter MoE model on a home server with a GTX 1650 (4 GB) generated only 6 tokens per second, and most of the serving configs were broken.
13/13tests passing
A toolkit that shows whether a WhatsApp integration is really official and who owns it, plus a webhook that verifies Meta's signature and never processes a message twice.
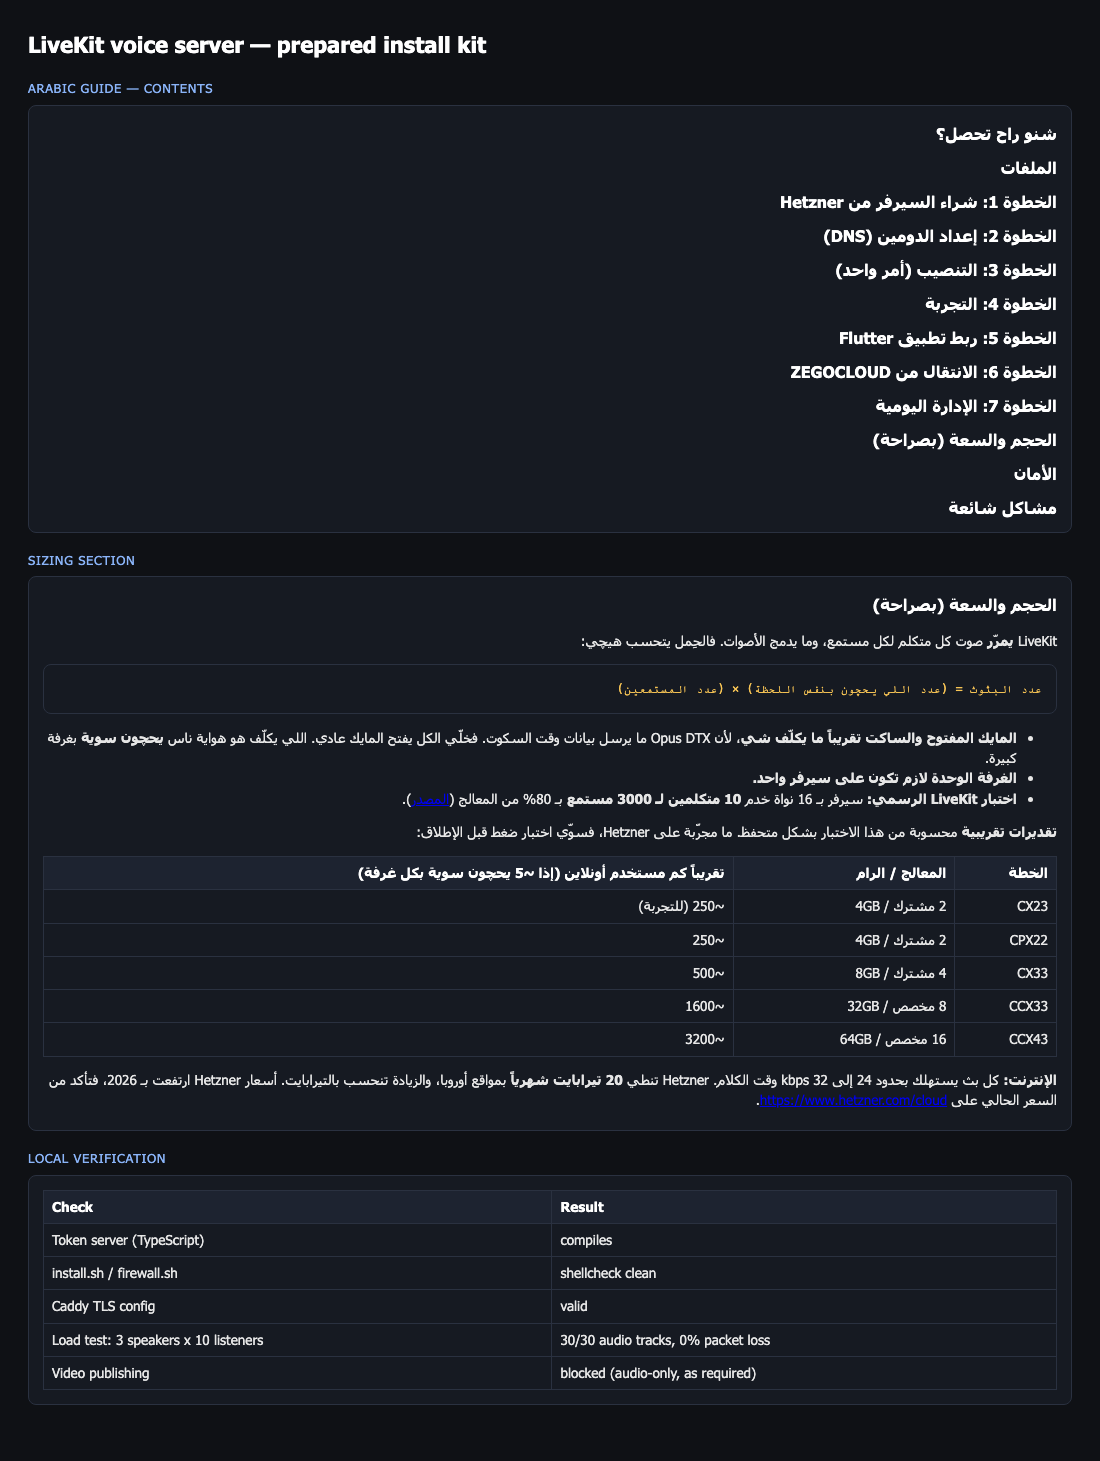
30/30audio tracks, 0% packet loss
Audio rooms on your own server instead of per-minute billing, with a one-command install and audio-only tokens.
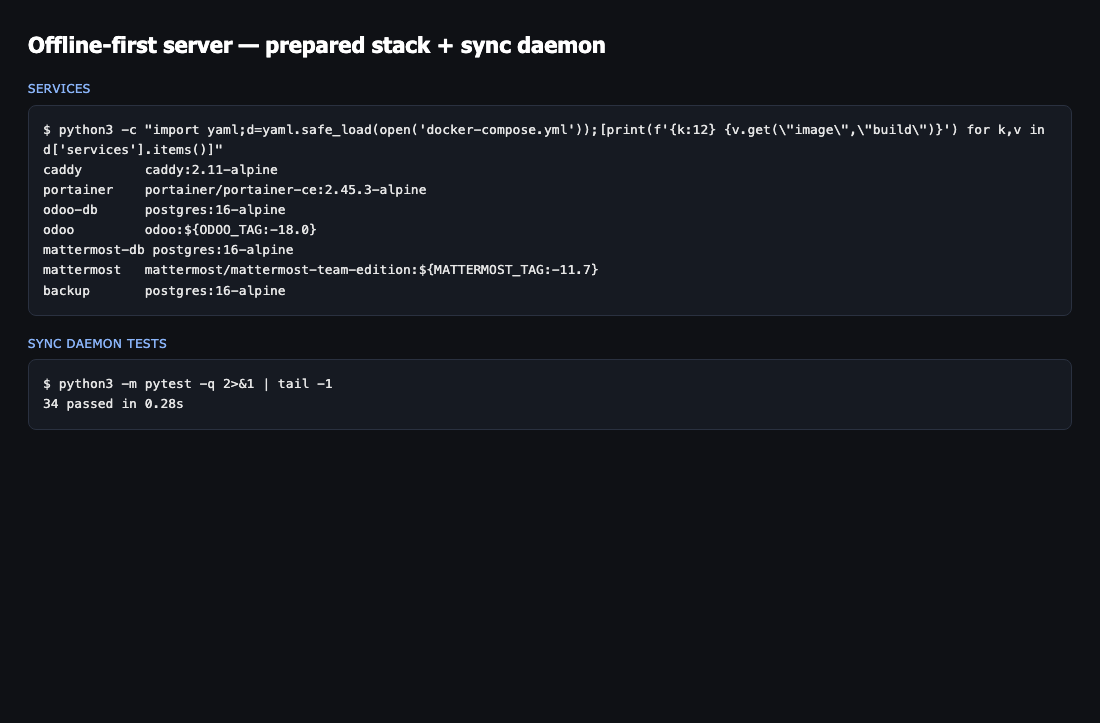
34tests passing
The shop always works on a local Odoo, and a background daemon pushes invoices and customers to the cloud when the internet returns, without duplicates.